Chapter 15 — Alignment: RLHF & Beyond
“Alignment is the difference between a model that can answer any question and one that should — it’s about making AI helpful, harmless, and honest.”
Why Alignment Matters
An SFT model follows instructions, but it may also: generate toxic content, make up facts confidently, comply with harmful requests, or be sycophantic. Alignment tunes the model’s behavior to match human preferences.
- Follows instructions but may be harmful
- Confidently wrong (hallucinations)
- No refusal behavior for dangerous requests
- May be verbose or sycophantic
- Refuses harmful requests appropriately
- Expresses uncertainty when unsure
- Balanced helpfulness vs safety
- Concise, honest responses
The RLHF Pipeline
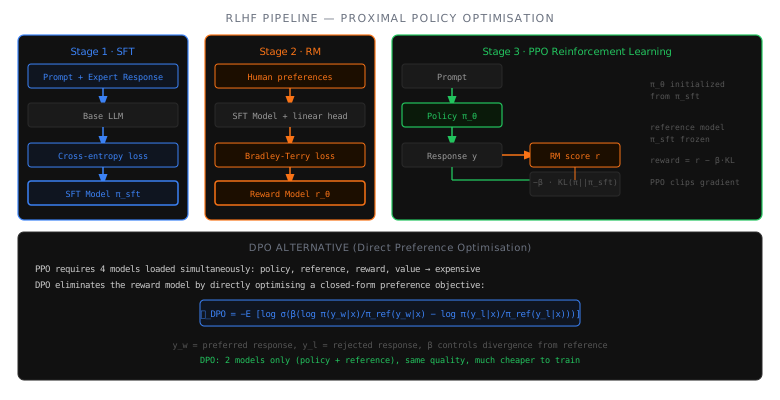
Reinforcement Learning from Human Feedback is the classic alignment approach, used in ChatGPT and Claude.
Stage 2: Reward Model
Human annotators compare pairs of model responses and pick the better one. These preferences train a reward model that predicts a scalar quality score:
\[\mathcal{L}_{\text{RM}} = -\log\sigma(R(x, y_w) - R(x, y_l))\]where $y_w$ is the preferred response and $y_l$ is the rejected response.
The reward model is typically initialized from the SFT model with the LM head replaced by a scalar head.
Stage 3: PPO Optimization
PPO (Proximal Policy Optimization) updates the policy (SFT model) to maximize reward while staying close to the original SFT model via a KL divergence penalty:
\[\mathcal{L}_{\text{PPO}} = \mathbb{E}\left[R(x, y) - \beta \cdot D_{\text{KL}}(\pi_\theta \| \pi_{\text{SFT}})\right]\]The KL penalty prevents reward hacking — where the model exploits the reward model’s weaknesses rather than genuinely improving.
RLHF requires 4 models in memory simultaneously (policy, reference, reward, value) — extremely expensive. This motivated simpler alternatives.
DPO — Direct Preference Optimization
DPO (Rafailov et al., 2023) eliminates the separate reward model and RL phase entirely. It directly optimizes the policy from preference pairs:
\[\mathcal{L}_{\text{DPO}} = -\log\sigma\!\left(\beta\left[\log\frac{\pi_\theta(y_w|x)}{\pi_{\text{ref}}(y_w|x)} - \log\frac{\pi_\theta(y_l|x)}{\pi_{\text{ref}}(y_l|x)}\right]\right)\]The key insight: the optimal RLHF policy has an analytical form that depends only on the log-probability ratio of the policy and reference model. No need for a separate reward model — the policy is the reward model.
- 4 models in memory
- Online sampling required
- Reward model training + PPO
- Hyperparameter sensitive
- Highest ceiling (with enough tuning)
- 2 models (policy + frozen reference)
- Offline — uses static preference dataset
- Single training stage
- Much simpler to implement
- Near-PPO quality for most use cases
DPO Training with TRL
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
from transformers import AutoModelForCausalLM, AutoTokenizer
from trl import DPOTrainer, DPOConfig
from datasets import load_dataset

model = AutoModelForCausalLM.from_pretrained(
    "your-sft-model",
    torch_dtype=torch.bfloat16,
    device_map="auto",
)
ref_model = AutoModelForCausalLM.from_pretrained(
    "your-sft-model",  # Same starting point — frozen
    torch_dtype=torch.bfloat16,
    device_map="auto",
)
tokenizer = AutoTokenizer.from_pretrained("your-sft-model")

# Preference dataset: each example has prompt, chosen, rejected
dataset = load_dataset("HuggingFaceH4/ultrafeedback_binarized", split="train_prefs")

training_args = DPOConfig(
    output_dir="./dpo-model",
    per_device_train_batch_size=2,
    gradient_accumulation_steps=8,
    learning_rate=5e-7,           # Very low LR for DPO
    beta=0.1,                     # KL penalty strength
    num_train_epochs=1,
    bf16=True,
    max_length=1024,
    max_prompt_length=512,
)

trainer = DPOTrainer(
    model=model,
    ref_model=ref_model,
    args=training_args,
    train_dataset=dataset,
    tokenizer=tokenizer,
)
trainer.train()
Other Alignment Methods
Comparison Table
| Method | Models Needed | Data Required | Complexity | Quality |
|---|---|---|---|---|
| PPO (RLHF) | 4 | Preferences + online | Very high | Highest ceiling |
| DPO | 2 | Preferences (offline) | Low | Near-PPO |
| KTO | 2 | Binary thumbs-up/down | Low | Good |
| ORPO | 1 | Chosen + rejected | Very low | Good |
| RLAIF | 2 + judge LLM | AI-generated preferences | Medium | Good (cheaper) |
| SimPO | 1 | Preferences | Very low | Near-DPO |
The Alignment Tax
Alignment improves safety but can slightly reduce raw capability (the “alignment tax”):
| Benchmark | Base Model | SFT | + DPO |
|---|---|---|---|
| MMLU | Baseline | +2–3% | +0–1% |
| GSM8K | Baseline | +5–10% | -0–2% |
| HumanEval | Baseline | +5–8% | -0–1% |
| TruthfulQA | Baseline | +10% | +15–20% |
| Toxicity ↓ | High | Medium | Low ✓ |
The alignment tax is real but small — and the safety and usability gains far outweigh it.
What’s Next
With training complete (pre-training → mid-training → SFT → alignment), we now move to inference — how models generate text token by token, and the sampling strategies that control output quality.
← Previous: Chapter 14 — PEFT: LoRA, QLoRA & Variants · Next: Chapter 16 — Inference & Sampling →
Last updated: April 2026