Chapter 14 — PEFT: LoRA, QLoRA & Variants
“You don’t need to update 7 billion parameters to teach a model new tricks. A few million trainable parameters, properly placed, can reshape model behaviour entirely.”
Why Parameter-Efficient Fine-Tuning?
Full fine-tuning updates all model weights — expensive in memory, time, and storage. PEFT methods train a small subset of parameters while keeping the base model frozen:
- All 8B parameters updated
- BF16 weights: 16 GB
- AdamW states (FP32): 64 GB
- Gradients: 32 GB
- Total: ~112+ GB → multi-A100
- Checkpoint: 16 GB per saved model
- ~13M trainable parameters (0.16%)
- Frozen weights: 16 GB
- LoRA states + grads: ~200 MB
- Total: ~18 GB → fits RTX 3090
- Checkpoint: ~26 MB (adapter only)
LoRA — Low-Rank Adaptation
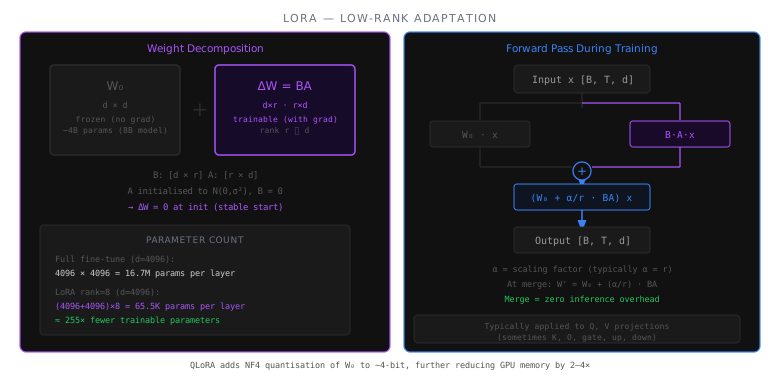
LoRA (Hu et al., 2021) is the most widely used PEFT method. It freezes all pre-trained weights and injects trainable low-rank decomposition matrices into targeted layers.
Mathematical Foundation
For a weight matrix W ∈ ℝ^(d×k), instead of updating it directly, LoRA adds a low-rank bypass:
where:
B ∈ ℝ^(d×r)— up-projection matrix, initialised to zeros (ensures zero output at init)A ∈ ℝ^(r×k)— down-projection matrix, initialised with random Gaussianr— rank (hyperparameter, typically 4–128)α— scaling factor (typically set equal tor, or 16)- Effective scaling:
α/rmultiplied byBA
The product BA has rank at most r, which is ≪ min(d, k) for large weight matrices.
Tensor Shapes Through LoRA
Which Layers to Apply LoRA To
LoRA can be applied to any linear layer. Common choices:
| Target Modules | Parameter Count | Notes |
|---|---|---|
q_proj, v_proj only |
Minimal | Original LoRA paper recommendation |
All attention: q, k, v, o |
Moderate | Better for most tasks |
All attention + FFN: gate, up, down |
Higher | Best quality, recommended by recent work |
| All linear layers | Maximum | Rarely needed |
Rank Selection
| Rank (r) | Trainable Params (8B) | Quality | Use Case |
|---|---|---|---|
| 4 | ~3M | Basic | Style transfer, simple classification |
| 8 | ~6M | Good | Standard instruction following |
| 16 | ~13M | Better | Code generation, complex reasoning |
| 32 | ~26M | Very good | Domain adaptation |
| 64 | ~52M | Near full FT | Challenging tasks |
| 128 | ~104M | Diminishing returns | Rarely necessary |
Rule of thumb: start with r=16, increase if quality is insufficient.
LoRA Merging
At inference time, LoRA adapters can be merged back into the base weights with zero overhead:
1
W_merged = W + (alpha / r) * B @ A  # shape [d, k]
After merging, there’s no inference latency penalty. This makes LoRA convenient for serving.
QLoRA — Quantized LoRA
QLoRA (Dettmers et al., 2023) enables fine-tuning of very large models on consumer GPUs by combining 4-bit quantisation with LoRA.
QLoRA Components
Base weights quantised to 4 bits using a data type optimised for normally distributed neural network weights
Quantise the quantisation constants themselves (saves ~0.37 bits/param extra)
Offload Adam optimizer states to CPU RAM during memory spikes (prefill/decode)
Trainable adapters remain in full precision; gradients computed in BF16
NF4 — Normal Float 4
NF4 is theoretically optimal for weights assumed to be normally distributed (N(0, σ²)):
- The 16 quantisation bins are placed at the quantiles of the standard normal distribution
- Equal probability mass in each bin → minimises quantisation error for normally distributed data
- vs INT4: NF4 has ~5% better quantisation error on typical neural network weights
The forward pass dequantises weights on-the-fly during matrix multiplication:
1
2
3
4
5
W_nf4: [d, k] in NF4 (4 bits/param)
  ↓ dequantize
W_bf16: [d, k] in BF16  ← temporary, for this operation only
  ↓ matmul with activations
output: [B, T, d] in BF16
QLoRA Memory Budget (LLaMA-3-8B)
| Component | Precision | Memory |
|---|---|---|
| Base weights | NF4 | 4.0 GB |
| LoRA A/B matrices | BF16 | 26 MB |
| Optimizer states (LoRA only) | FP32 | 52 MB |
| Activations | BF16 | ~1–2 GB |
| Total | — | ~5–6 GB |
Compare to full fine-tuning: ~112 GB. QLoRA fits on a single RTX 4090 (24 GB VRAM).
QLoRA Practical Setup
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
from transformers import AutoModelForCausalLM, BitsAndBytesConfig
from peft import get_peft_model, LoraConfig, prepare_model_for_kbit_training

# 4-bit quantisation config
bnb_config = BitsAndBytesConfig(
    load_in_4bit=True,
    bnb_4bit_compute_dtype=torch.bfloat16,
    bnb_4bit_quant_type="nf4",
    bnb_4bit_use_double_quant=True,
)

model = AutoModelForCausalLM.from_pretrained(
    "meta-llama/Llama-3.1-8B",
    quantization_config=bnb_config,
    device_map="auto",
)

# Prepare model for training (handles frozen base + trainable LoRA)
model = prepare_model_for_kbit_training(model)

# Add LoRA adapters
lora_config = LoraConfig(
    r=16,
    lora_alpha=32,
    target_modules=["q_proj", "k_proj", "v_proj", "o_proj",
                    "gate_proj", "up_proj", "down_proj"],
    lora_dropout=0.05,
    task_type="CAUSAL_LM",
)
model = get_peft_model(model, lora_config)
model.print_trainable_parameters()
# trainable params: 13,631,488 || all params: 8,044,765,184 || trainable%: 0.17
DoRA — Weight-Decomposed LoRA
DoRA (Liu et al., 2024) decomposes weights into magnitude and direction, applying LoRA only to the directional component:
\[W' = \underbrace{m}_{\text{learnable magnitude}} \cdot \underbrace{\frac{W + BA}{\|W + BA\|_c}}_{\text{normalised direction (LoRA-updated)}}\]where ‖·‖_c denotes column-wise normalisation and m ∈ ℝ^(1×k) is a learnable vector.
Why it works: full fine-tuning tends to update both magnitude and direction together. DoRA explicitly factorises this, giving LoRA the ability to independently adjust both — closing the gap to full fine-tuning.
Benchmarks: DoRA consistently matches or exceeds full fine-tuning quality at the same LoRA rank, especially on instruction following and commonsense reasoning.
LoRA Variants Comparison
| Method | Core Idea | Params | vs LoRA Quality | Notes |
|---|---|---|---|---|
| LoRA | Low-rank BA decomposition | r(d+k) | Baseline | Standard, widely supported |
| QLoRA | LoRA + NF4 quantised base | r(d+k) | Similar | Enables large models on small GPUs |
| DoRA | Magnitude-direction decomposition | r(d+k)+k | Better | Closes gap to full FT |
| LoRA+ | Different LR for A and B matrices | r(d+k) | Slightly better | Simple improvement |
| rsLoRA | Scale by 1/√r instead of 1/r | r(d+k) | Better at high r | More stable rank scaling |
| LoKr | Kronecker product decomposition | Varies | Similar | Lower rank expressivity |
| VeRA | Shared A/B with per-layer scaling | Very small | Similar | Extreme parameter efficiency |
| LoRA-FA | Freeze A, only train B | r×d | Slightly worse | Half the memory of LoRA |
| MoLoRA | Mixture of LoRA experts | r(d+k)×E | Better | Multiple specialised adapters |
Other PEFT Methods
Adapters (Houlsby et al., 2019)
Small bottleneck MLPs inserted after attention and FFN layers:
1
Input → Attention → [Adapter: down-project → activation → up-project] → LayerNorm → ...
Tensor shapes:
- Down-project:
[d_model, r_adapter]e.g.,[4096, 64] - Up-project:
[r_adapter, d_model]e.g.,[64, 4096]
Drawback: adds sequential computation → inference latency (can’t be merged like LoRA).
Prefix Tuning (Li & Liang, 2021)
Prepend learnable “virtual tokens” to the key and value sequences at each layer:
1
2
K' = [P_K ; K]   shape: [B, H, n_prefix + T, d_head]
V' = [P_V ; V]   shape: [B, H, n_prefix + T, d_head]
The prefix P_K, P_V ∈ ℝ^(n_prefix × d_head) are learned per task. No weight changes to the model.
Drawback: reduces effective context length by n_prefix.
Prompt Tuning (Lester et al., 2021)
The simplest PEFT method: prepend learnable embeddings to the input:
1
2
input_embeds = [P ; embed(tokens)]
# P shape: [n_prefix, d_model]  e.g., [20, 4096] = 82K trainable params
At scale (≥10B params), prompt tuning approaches full fine-tuning quality. Very fast — only ~10K–100K params.
IA³ — Infused Adapter by Inhibiting and Amplifying Inner Activations
Learn scaling vectors for keys, values, and FFN activations:
1
2
3
K' = l_K ⊙ K    # element-wise scaling, l_K shape: [d_head]
V' = l_V ⊙ V    # same
FFN_out' = l_FF ⊙ FFN_out
Even fewer parameters than LoRA — roughly 0.01% of model parameters. Good for few-shot adaptation.
Choosing the Right PEFT Method
| Factor | LoRA | QLoRA | DoRA | Adapters | Prompt Tuning |
|---|---|---|---|---|---|
| Trainable % | 0.1–1% | 0.1–1% | 0.1–1%+ | 1–3% | <0.01% |
| Memory (8B) | ~18 GB | ~6 GB | ~18 GB | ~20 GB | ~18 GB |
| Inference latency | None (merge) | None (merge) | None (merge) | +5–10% | +minor |
| Quality vs full FT | 95–99% | 90–97% | ~99% | 95–99% | 90–97% (large) |
| Multi-task swap | Swap adapter | Swap adapter | Swap adapter | Swap adapter | Swap prefix |
| Framework support | ★★★★★ | ★★★★★ | ★★★★ | ★★★ | ★★★ |
LoRA in Practice: Common Pitfalls
-
Wrong target modules: applying LoRA only to
q_projandv_projis common but suboptimal — include all projection matrices including FFN for best results -
Rank too low for complex tasks:
r=4may be insufficient for code generation or domain-heavy tasks; start atr=16 -
Alpha scaling:
alpha = ris a safe default (effective scale = 1). Some practitioners setalpha = 2*rfor slightly faster convergence -
Forgetting to merge before deployment: serving with active LoRA adapters adds a forward-pass overhead vs merging once and discarding the adapter
-
QLoRA for small models: quantisation overhead (dequant on-the-fly) slows training; only worthwhile for models ≥13B where memory savings matter
What’s Next
Fine-tuning makes models capable; alignment makes them behave. The next chapter covers RLHF, DPO, and how to shape model values and safety.
← Previous: Chapter 13 — Fine-Tuning & Adaptation · Next: Chapter 15 — Alignment: RLHF & Beyond →
Last updated: April 2026