Chapter 4 — Attention Deep Dive: SDPA & Multi-Head Attention
“The key innovation of attention is allowing the model to dynamically focus on relevant parts of the input, rather than compressing everything into a fixed-size vector.”
Scaled Dot-Product Attention (SDPA)
Attention is the mechanism that lets each token look at every other token in the sequence and decide what’s relevant. At its core, it’s a soft lookup: queries ask questions, keys advertise content, and values hold the actual information.
Given three matrices — Query (Q), Key (K), and Value (V) — scaled dot-product attention computes:
\[\text{Attention}(Q, K, V) = \text{softmax}\!\left(\frac{QK^T}{\sqrt{d_k}}\right) V\]Tensor Shapes Through SDPA
Why Scale by √d_k?
Without scaling, the dot product of Q and K grows proportionally to d_k. Large dot products push softmax into saturated regions where gradients vanish. Dividing by √d_k keeps the variance of the scores at ~1 regardless of dimension:
If $q_i, k_i \sim \mathcal{N}(0, 1)$, then $\text{Var}(q \cdot k) = d_k$. After scaling: $\text{Var}!\left(\frac{q \cdot k}{\sqrt{d_k}}\right) = 1$.
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
import torch
import torch.nn.functional as F

def scaled_dot_product_attention(Q, K, V, mask=None):
    """
    Q, K, V: [B, H, T, d_k]
    mask: [T, T] or [B, 1, T, T] — True means IGNORE
    Returns: [B, H, T, d_k]
    """
    d_k = Q.shape[-1]
    scores = torch.matmul(Q, K.transpose(-2, -1)) / (d_k ** 0.5)  # [B, H, T, T]

    if mask is not None:
        scores = scores.masked_fill(mask, float('-inf'))

    weights = F.softmax(scores, dim=-1)  # [B, H, T, T]
    output = torch.matmul(weights, V)    # [B, H, T, d_k]
    return output, weights
Causal Masking
In decoder-only models (GPT, LLaMA), each token can only attend to itself and previous tokens — it must not see the future. This is enforced with a causal mask: an upper-triangular matrix of −∞ values that, after softmax, zero out attention to future positions.
- ✓ · · · ·
- ✓ ✓ · · ·
- ✓ ✓ ✓ · ·
- ✓ ✓ ✓ ✓ ·
- ✓ ✓ ✓ ✓ ✓
- 1.0 0 0 0 0
- 0.6 0.4 0 0 0
- 0.2 0.3 0.5 0 0
- 0.1 0.2 0.3 0.4 0
- 0.1 0.1 0.2 0.3 0.3
1
2
3
4
5
6
7
8
9
10
def causal_mask(T, device='cpu'):
    """Returns a boolean mask: True = masked (ignored)."""
    return torch.triu(torch.ones(T, T, dtype=torch.bool, device=device), diagonal=1)

mask = causal_mask(5)
# tensor([[False,  True,  True,  True,  True],
#         [False, False,  True,  True,  True],
#         [False, False, False,  True,  True],
#         [False, False, False, False,  True],
#         [False, False, False, False, False]])
Multi-Head Attention (MHA)
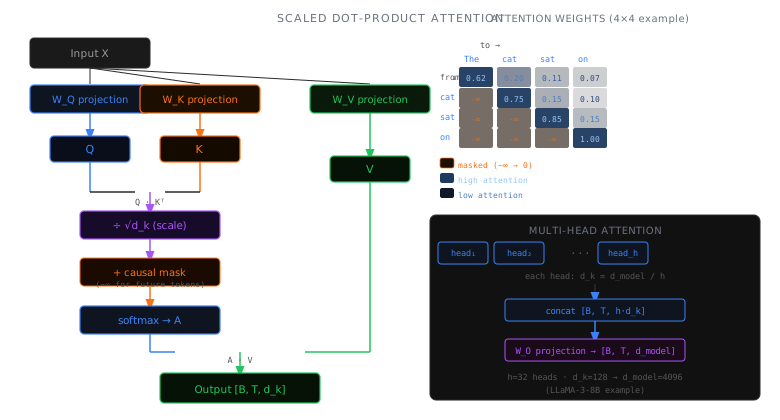
Instead of computing a single attention function, multi-head attention runs H parallel attention operations (called “heads”), each on a different d_k-dimensional subspace. This lets different heads learn different types of relationships (syntactic, semantic, positional, etc.).
For LLaMA-3-8B: d_model = 4096, H = 32 heads, d_k = 4096/32 = 128 per head.
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
class MultiHeadAttention(nn.Module):
    def __init__(self, d_model, n_heads):
        super().__init__()
        self.n_heads = n_heads
        self.d_k = d_model // n_heads

        self.W_q = nn.Linear(d_model, d_model, bias=False)
        self.W_k = nn.Linear(d_model, d_model, bias=False)
        self.W_v = nn.Linear(d_model, d_model, bias=False)
        self.W_o = nn.Linear(d_model, d_model, bias=False)

    def forward(self, x, mask=None):
        B, T, _ = x.shape

        # Project and reshape: [B, T, d_model] → [B, H, T, d_k]
        Q = self.W_q(x).view(B, T, self.n_heads, self.d_k).transpose(1, 2)
        K = self.W_k(x).view(B, T, self.n_heads, self.d_k).transpose(1, 2)
        V = self.W_v(x).view(B, T, self.n_heads, self.d_k).transpose(1, 2)

        # Scaled dot-product attention per head
        attn_out, _ = scaled_dot_product_attention(Q, K, V, mask=mask)  # [B, H, T, d_k]

        # Concatenate heads: [B, H, T, d_k] → [B, T, d_model]
        concat = attn_out.transpose(1, 2).contiguous().view(B, T, -1)

        # Final projection
        return self.W_o(concat)  # [B, T, d_model]
Self-Attention vs Cross-Attention
- Q, K, V all come from the same sequence
- Each token attends to all other tokens in the sequence
- Used in both encoder and decoder
- Decoder uses causal masking
- Q from decoder, K and V from encoder
- Decoder tokens attend to encoder representations
- Used in encoder-decoder models (T5, BART)
- Not present in decoder-only models (GPT, LLaMA)
In self-attention, the query, key, and value all come from the same input. In cross-attention, Q comes from one sequence (decoder) while K and V come from another (encoder output). Decoder-only models like GPT and LLaMA use only self-attention.
Flash Attention
The attention score matrix [B, H, T, T] is O(T²) in memory. For T = 128K tokens with 32 heads and FP16, that’s 128K × 128K × 32 × 2 bytes = 1 TB — far too large to materialize. Flash Attention (Dao et al., 2022) solves this by:
- Tiling: Compute attention in small blocks that fit in GPU SRAM (shared memory)
- Online softmax: Compute softmax incrementally without materializing the full score matrix
- Kernel fusion: Fuse the matmul, softmax, and output matmul into a single GPU kernel
In practice, you almost never implement attention yourself. PyTorch provides an optimized implementation that auto-selects the best backend (Flash Attention, memory-efficient attention, or math fallback):
1
2
3
4
5
6
7
8
9
import torch.nn.functional as F

# PyTorch's optimized SDPA — automatically uses Flash Attention when available
output = F.scaled_dot_product_attention(
    Q, K, V,                    # [B, H, T, d_k]
    attn_mask=None,
    is_causal=True,             # applies causal mask internally
    dropout_p=0.0,
)  # → [B, H, T, d_k]
Attention Head Specialization
Different heads learn to attend to different things. Research has shown that transformer heads naturally specialize:
| Head Type | What It Learns | Example |
|---|---|---|
| Positional | Attend to nearby tokens | “the → cat” (adjacent word) |
| Syntactic | Subject-verb agreement | “The cats → are” (long-range grammar) |
| Copying | Attend to identical or similar tokens | Repetitions, references |
| Induction | [A][B]…[A] → predict [B] | In-context learning patterns |
| Rare/dead | Low-entropy, nearly uniform | Some heads are redundant |
Understanding head specialization is important for attention variant design — some heads are more important than others, which motivates the grouped and multi-query approaches in Chapter 5.
What’s Next
Standard multi-head attention gives each head its own Q, K, and V projections — but this creates a memory bottleneck when caching K and V during inference. The next chapter explores how modern models address this with grouped-query attention (GQA), multi-query attention (MQA), and multi-latent attention (MLA).
← Previous: Chapter 3 — The Transformer · Next: Chapter 5 — GQA, MQA & MLA →
Last updated: April 2026